New research: Leading indicators of AI coding agent effectiveness
New research: Leading indicators of AI coding agent effectiveness
The Effectiveness Scorecard: A Clearer View of Where to Focus
News
Span Team
Span Team
ON THIS PAGE
Yesterday, we introduced Span’s AI Effectiveness suite, built on agent traces and agent evals.
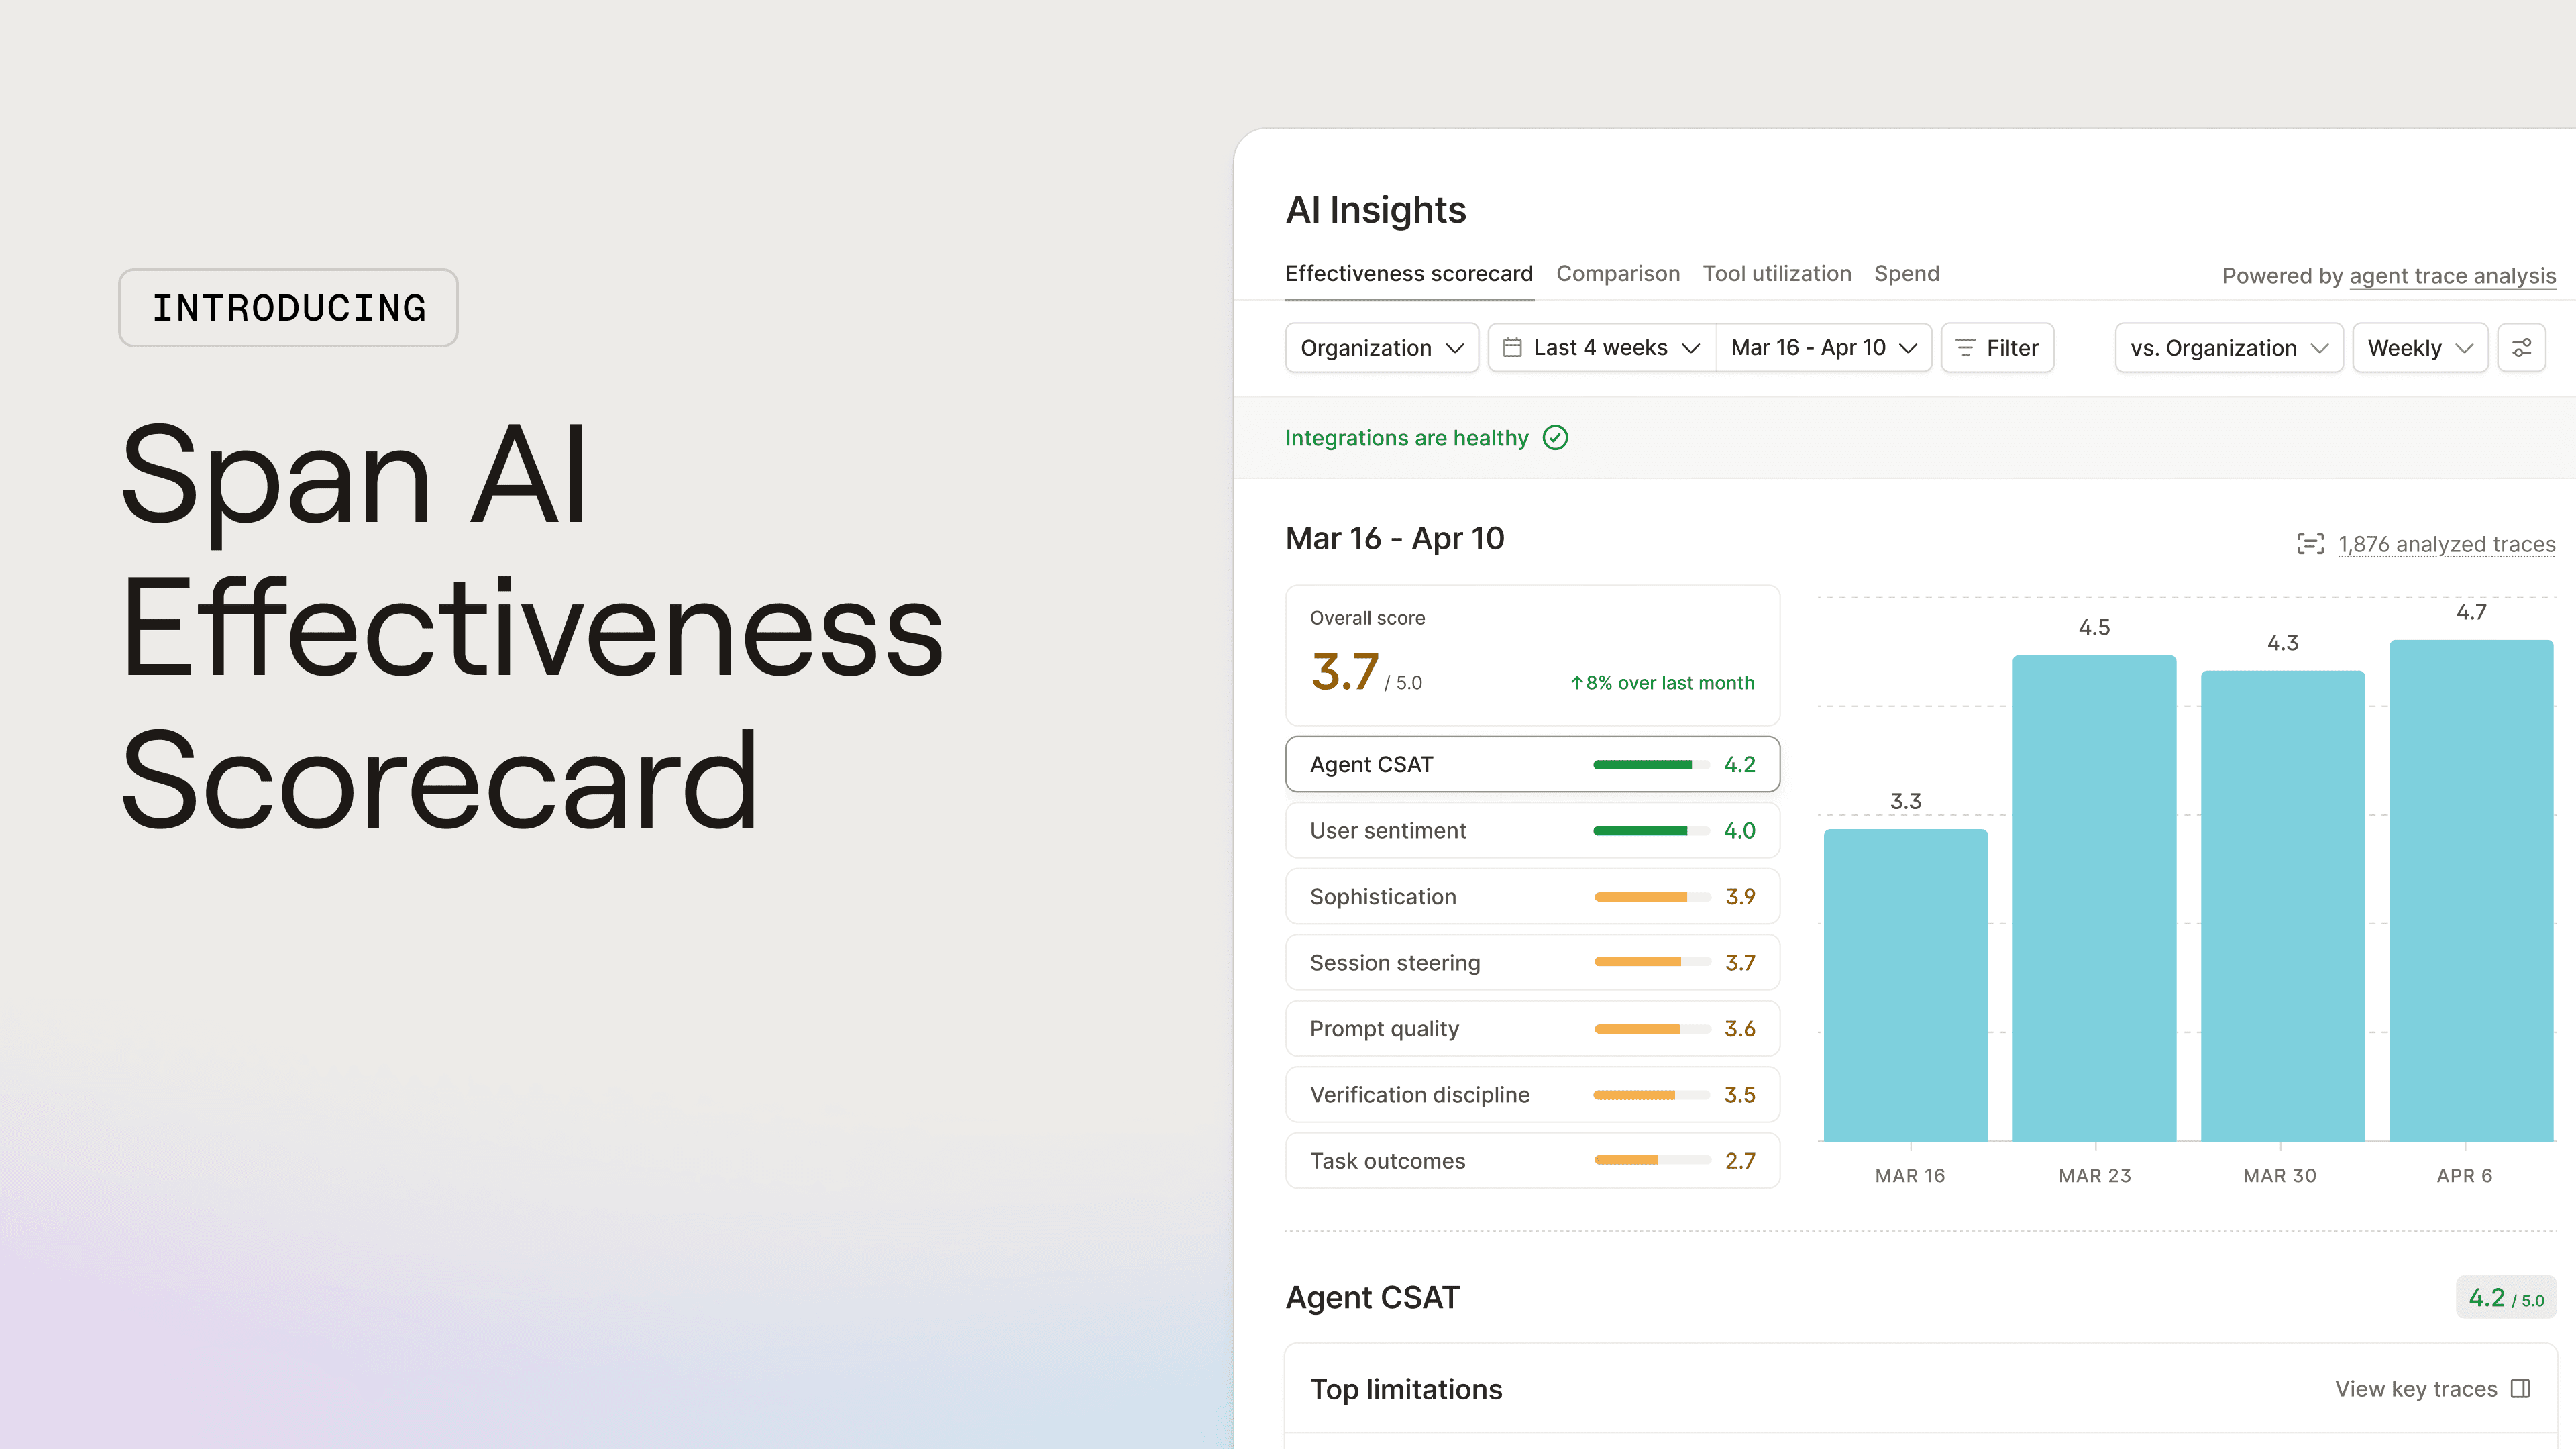
The first experience we’re unveiling is the Effectiveness Scorecard: a leadership-level view of how AI effectiveness is trending across the organization, where gaps are emerging, and where to focus next.
It gives engineering leaders a clear baseline for understanding AI effectiveness and how it changes over time.
Built on Agent Traces and Evals
Built on Agent Traces and Evals
Built on Agent Traces and Evals
The Effectiveness Scorecard is powered by agent traces: the interaction history between developers and AI tools, including prompts, iterations, tool calls, file edits, and more. Span analyzes those traces and applies agent evals across sessions to synthesize patterns across interaction history.
That gives leaders a more direct view of effectiveness than usage metrics alone. Instead of just seeing whether AI is being used, they can see how effectively teams are working with it.
What Leaders See
What Leaders See
What Leaders See
At the center of the report are org-level scores across key dimensions—like user sentiment, agent satisfaction, prompt quality, and other signals that shape AI effectiveness in practice.
Beyond the scores, the report surfaces the context leaders need to understand why and what to do next:
Trends over time
See how effectiveness is changing across the organization and establish a measurable baseline for improvement.
Patterns by team or topic
Filter by team, theme, or area to understand where stronger or weaker patterns are emerging.
Top contributing traces
Drill down from a lower score or recurring issue into the traces that contributed most to it.
Common friction and blockers
Surface recurring signs of user frustration, workflow breakdowns, or environmental issues that are making agents less effective.
Supporting context
Bring in related signals like repository health and emerging patterns that help explain why effectiveness looks the way it does.
A Practical Starting Point
A Practical Starting Point
A Practical Starting Point
Effectiveness scores give leaders a baseline. The value is in the context, patterns, and recommendations that show where to focus next. More soon on how teams can turn that understanding into continuous improvement.
Next post in this series: Introducing Spotlights
A Practical Starting Point
Effectiveness scores give leaders a baseline. The value is in the context, patterns, and recommendations that show where to focus next. More soon on how teams can turn that understanding into continuous improvement.
Next post in this series: Introducing Spotlights
Learn More
Frequently asked questions
Frequently asked questions
What counts as a contributor?
A contributor is anyone who commits code or is tracked across your connected tools (e.g., GitHub, GitLab). Non-engineering users like PMs or executives who only view dashboards are free.
Do you offer volume discounts?
Is there a minimum contract term?
Do you offer services and support?
Can I try Span before committing?
Let's talk about where your AI program is.


platform
© 2026 Attuned Inc.


Let's talk about where your AI program is.
platform
© 2026 Attuned Inc.
Let's talk about where your AI program is.
platform
© 2026 Attuned Inc.